Extract targeted data
/extract fills a table from your documents, one value per cell, each value linked to the page it came from. It works in two modes and picks the mode from the table you select. There is no setting.
Extraction or matching
Filled columns are keys. Empty columns with a title are filled from the documents.
| Extraction | Matching | |
|---|---|---|
| For | Building a table from a batch of documents, when you have no list yet | Testing rows you already have (a ledger sample): finding the supporting document of each row |
| Your table | Precise titles, one value per column, nothing under the header | Your rows with filled key columns (reference, date, counterparty, amount) and empty titled columns for the document values |
| You select | Only the header rows: the titles, plus the description row if there is one | The whole table: header rows and every data row |
| Moby writes | One new row per document, under the header | The empty cells of each matched row. A filled cell is never overwritten |
| Document column | The file of each row | The file or files matched to each row |
Run it
- In the Workflows tab, click Extract targeted data, or type
/extractin the chat. - Step 1/2. Choose the documents: Upload new ones or Change the selection, then Next.
- Step 2/2. Select the table in the sheet. The card shows the range and its size.
- Click Launch. The card shows the progress and lets you cancel.
- When the card says Extraction complete, click any value: the Preview tab opens the source page with the value highlighted.
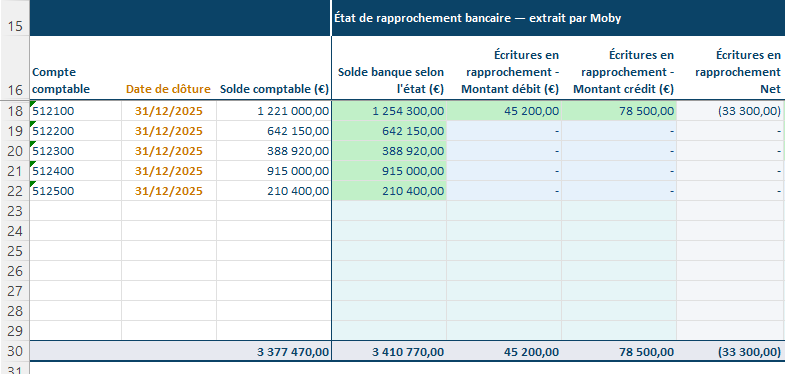
A bank reconciliation sheet after a matching run: the block on the right was filled from the reconciliation statements, one document per row.
If Moby is unsure how to read the table, it stops before the run with Before I continue and says why. Choose Continue anyway, or Cancel & fix to correct the sheet and launch again.
The header rows
From top to bottom. The data starts right under the last header row.
| Row | What goes in it | Extraction | Matching |
|---|---|---|---|
| Category | A merged label over each block: the ledger block (Accounting) and one block per document type (Invoice, Delivery note, Bank statement) | None | Required with several document types, optional otherwise |
| Column title | One precise title per column, one value per column | Required | Required |
| Description | A hint under a title that could be read two ways ("incl. VAT, bottom right of the invoice"). It becomes part of the instruction for that column | Optional | Optional |
Extraction takes two header rows at most. Matching takes three at most: one category level only.
What Moby writes
| Where | What |
|---|---|
| The empty cells of the table | The values, one per cell, each linked to its source page |
| A Document column, one column to the right of the table | The file of each row. In matching, every file matched to the row |
| An Unmatched documents sheet, created only when needed | The documents that could not be placed: not matched, duplicate or failed. One line per document, with its result and the table it was run on |
A row with no document stays empty.
Several documents for one row, one document for several rows
| Case | What happens |
|---|---|
| Several documents match one row (two delivery notes for one order) | Texts are joined, numbers are added up, and the Document cell lists every file. The Preview shows Source 1/N: check each source and break the link with the one that does not belong |
| One document matches several rows (one invoice booked on two ledger lines) | The document is matched to each of those rows |
Existing values
- Inside your selection, a cell holding a value when you launch is never overwritten: filled keys, values from a previous run, your own entries.
- A formula column is skipped. A formula that shows an empty result counts as an empty cell.
- Outside the selection nothing is checked. In extraction, Moby writes its rows under the header over whatever is there: keep those rows free.
- On a first run, cells already present where the Document column lands are shifted to the right. On a new run, the previous Document column is reused.
- Correct values once the run is finished. A value corrected during the run is replaced by the final write.
Two examples
Extraction, with both header rows. Select A1:D2.
| A | B | C | D | |
|---|---|---|---|---|
| 1 | Invoice no. | Invoice date | Supplier | Amount incl. VAT |
| 2 | top right | DD/MM/YYYY | as printed on the invoice | number only |
| 3 | empty: one row per document from here |
Matching, with the three header rows. Select the whole table, A1:F4.
| A | B | C | D | E | F | |
|---|---|---|---|---|---|---|
| 1 | Accounting (merged A1:C1) | Invoice (merged D1:F1) | ||||
| 2 | Entry ref | Customer | Amount excl. VAT | Invoice no. | Customer | Amount excl. VAT |
| 3 | top right | name printed on the invoice | excl. VAT, number only | |||
| 4 | 5351200093 | Spécialités Pharma | 46,348 |
Columns A to C are filled: they are the keys. Columns D to F are empty: they are filled from the invoice. E and F are the twins of B and C, so you compare the ledger and the invoice side by side.
Limits
| Limit | |
|---|---|
| Documents per run | 200 by default. Your firm's limit may be higher |
| Pages per document | 200 |
| Columns | 30 |
| Rows | 400 |
| Characters per cell | 5,000 |
No totals: extract the values, then sum in Excel.
Learn more
- Your first dive runs both modes on sample documents.
- Build a good table lists the rules and the common mistakes.
- Ask the agent to check a table before a run: "check my table before extracting".